Date: November 02, 2026
When Averaging Is Not Enough: Coordinating Distributed Learning Systems
Author: Roberto Morales
Modern machine learning often begins with an implicit assumption: somewhere, somehow, data can be brought together. But in many of the settings where artificial intelligence (AI) is most needed—such as in hospitals, banks, public agencies, mobile devices, and sensor networks—the data cannot simply be pooled. Data in these environments are private, fragmented, legally constrained, and statistically heterogeneous.
Consider a group of hospitals that would like to build a shared predictive model (see Figure 1). Each hospital has its own patients, its own data distribution, and its own priorities. One may care most about early detection; another may wish to reduce false alarms; a third may need to control disparities across patient groups. At the same time, a central health authority may impose broader requirements such as safety, robustness, transparency, and regulation across the participating hospitals.
In what follows, we use “decentralized” in a broad sense: data and computation are distributed across agents, with a coordinating mechanism that may still exist. More precisely, the architecture is close to federated learning with an explicit coordination layer, rather than a fully peer-to-peer system.
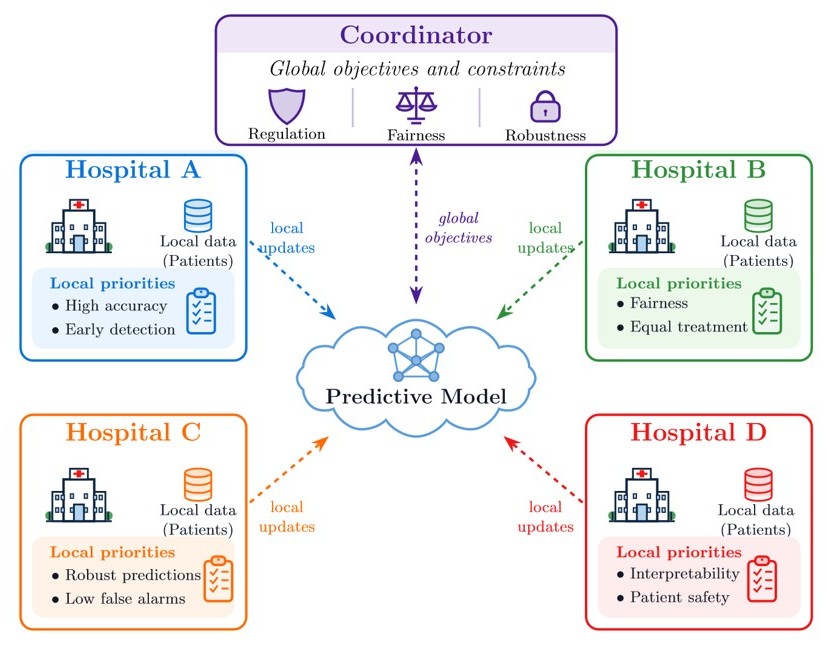
Figure 1. A hospital-inspired view of decentralized learning. Local institutions keep their data private, while a coordinator represents system-level requirements such as regulation, fairness, and robustness. Figure courtesy of the author.
Averaging is Not a Neutral Option
A better way to approach the problem is first to stop treating decentralized learning as a single-objective task. Each agent will solve a local learning problem shaped by its own data and priorities. The system, however, must also satisfy global requirements for fairness, stability, robustness, interpretability, or compliance with external rules.
Mathematically, the key point is to recognize that these different goals cannot, in general, be compressed into a single number without losing information about their tradeoffs. Each hospital has its own loss, and the coordinator may add system-level criteria.
Suppose that M agents train a shared model with \Theta parameters Agent i has a local loss C_i(\Theta) while the coordinator evaluates global criteria
S_1(\Theta), \dots, S_N(\Theta),
which may represent fairness, robustness, stability, or regulatory constraints. A fairness term might penalize large discrepancies in error rates across patient groups; a robustness term might penalize sensitivity of the model to small perturbations; and a stability term might discourage successive local models from drifting too far apart.
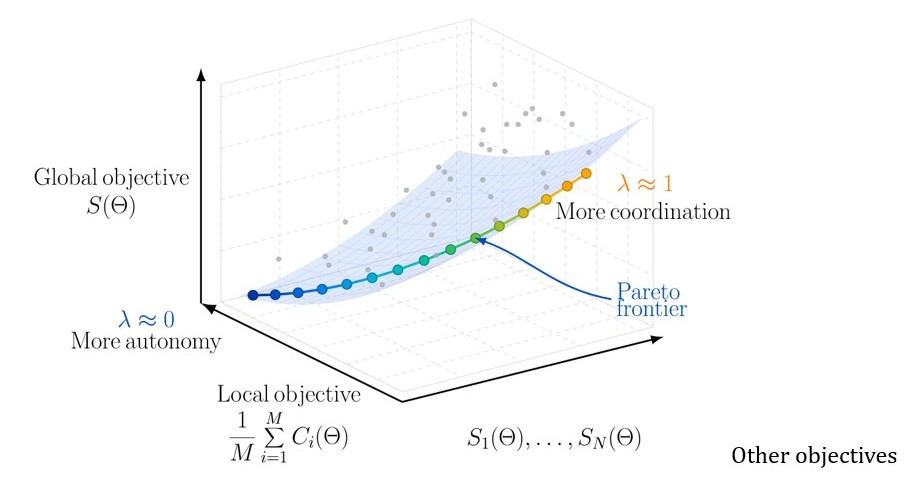
Figure 2. The tradeoff landscape of coordinated decentralized learning. Moving along the Pareto frontier changes the balance between local autonomy and global coordination. Figure courtesy of the author.
A coordinated formulation is
\min_{\Theta} (C_1(\Theta), \dots, C_M(\Theta), S_1(\Theta), \dots, S_N(\Theta)).
Since one cannot generally minimize all objectives in (1) at once, one may select a compromise through scalarization:
\min_{\Theta} \left\{ \frac{1-\lambda}{M} \sum_{i=1}^{M} C_i(\Theta) + \frac{\lambda}{N} \sum_{j=1}^{N} S_j(\Theta) \right\}, \quad 0 \le \lambda \lt 1.
The parameter \lambda acts as a coordination knob: small values favor local autonomy, while larger values give more influence to the coordinator.
The problem presented in (2) is not meant to eliminate the conflict among objectives, but it instead presents a way to choose one point among many possible compromises. Scalarization is only the simplest way to select compromises, and more general multi-objective methods may be needed when the tradeoff geometry is nonconvex.
The set of meaningful compromises is often called the Pareto frontier (see Figure 2) [3]. Each point on this frontier represents a model for which no objective can be improved without sacrificing at least one other objective. Thus, the relevant question is not whether local autonomy or global coordination should dominate, but where the right compromise lies.
What Does the Coordinator Actually Do?
The coordinator does not need to see the raw data. Instead, it can send global penalties, weights, constraints, or correction signals that modify the local training objectives so that each agent still trains locally, but not in isolation.
A simple implementation is to replace the local loss C_i by a coordinated loss of the form
F_i(\Theta) = C_i(\Theta) + \alpha \sum_{j=1}^{N} S_j(\Theta), \quad \alpha = \frac{\lambda}{(1 - \lambda)N}, \quad 0 \le \lambda \lt 1.
Local training directions are therefore no longer determined only by local data, they are tilted by the global objectives supplied by the coordinator before the local models are aggregated.
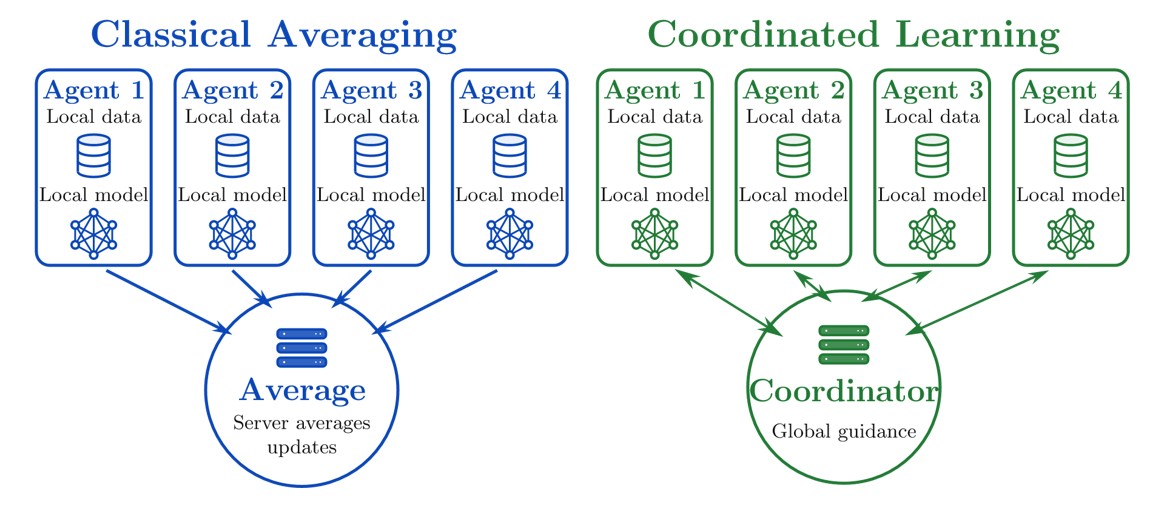
Figure 3. From averaging to coordination. Classical federated learning aggregates local updates after training, while coordinated learning lets global requirements influence the local update step. Figure courtesy of the author.
This is the conceptual difference between classical averaging and coordinated learning (see Figure 3). In classical federated averaging, coordination appears mainly after local training, through the aggregation step. Conversely, in coordinated learning, global objectives already shape the local updates themselves.
This is close to how real institutions operate. A hospital does not make decisions based only on internal statistics, it also follows clinical guidelines, legal rules, ethical principles, and safety standards set by governing organizations. These global rules do not replace local knowledge; they shape how local knowledge is used.
When No One Sees the Full Picture
To illustrate this idea, consider a deliberately difficult version of handwritten-digit classification on MNIST. Five agents are asked to train a shared model, but each agent sees examples from only two of the 10-digit classes:
\{2,8\}\{4,9\}\{1,6\}\{3,7\}\{0,5\}
No single agent sees the full 10-class problem. This mimics the hospital example, as each institution observes only a partial view of the global population. Each agent trains the same 10-class network, but its local batches contain examples from only two classes. Thus, the global model must be assembled from partial and biased views of the classification task.
The model is a convolutional neural network trained for 50 communication rounds. Each agent performs one local epoch per round, which helps reduce the risk of agent drift. The global model is then evaluated on the full 10-class MNIST test set. The coordinator uses a simple regularization objective whose role is not to create missing data, but to prevent local models from moving too far toward narrow, agent-specific solutions. The results of the experiments are summarized in Figure 4 [4].
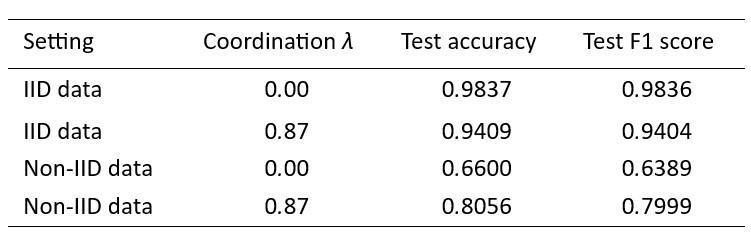
Figure 4. Effect of the coordination parameter in independent and identically distributed (IID) and non-IID settings. In the IID case, strong coordination slightly reduces performance; in the non-IID case, where each agent sees only two digits, coordination improves global test performance. Figure courtesy of the author.
When the data are independent and identically distributed (IID), the agents already see representative samples of the global problem; too much coordination can therefore slow or distort local learning. But when the data are highly non-IID, coordination becomes useful. It limits the tendency of each agent to specialize excessively in its own two digits and helps the global model generalize beyond any single local distribution.
The goal is not to outperform a fully centralized model that sees all the data at once. Centralized learning has full access, while decentralized learning must work under privacy, fragmentation, and communication constraints. The goal of decentralized learning is to build a useful shared model under privacy, data fragmentation, and communication constraints while also balancing local and global objectives.
Outlook
The future of AI will not be built solely in centralized data centers. Many important societal applications and institutions involve distributed and sensitive data from hospitals, banks, and research institutions, to mobile devices, industrial systems, and sensor networks.
In these settings, decentralized learning is not only a matter of efficiency, it is also a matter of governance. Who decides what a shared model should optimize? How should local accuracy be balanced against fairness, robustness, and regulation? How do we select a model that is acceptable both locally and globally?
These questions cannot be answered by averaging alone. A multi-objective viewpoint makes the tradeoffs visible and gives the coordinator precise mathematical roles: make competing objectives explicit,
navigate the Pareto frontier, and select compromises that reflect both local data and system-level requirements.
Decentralized learning is not only about training many local models; it is about helping many different learners build one model together. In this sense, its mathematics is not only the mathematics of optimization, but it represents the mathematics of compromise.
References